New to Rust? Grab our free Rust for Beginners eBook Get it free →
4 Things to Know About Utilizing MLOps

Moving a machine-learning model from experimentation into an application raises questions about how the system will be released and maintained. MLOps is the engineering practice of developing, releasing and maintaining systems that produce machine-learning predictions.
I’ll explain how MLOps covers the full lifecycle, then walk through putting a model into use, from input checks to a recorded release decision.
TL;DR
MLOps is the set of engineering practices that makes a machine-learning system repeatable, releasable and observable after a model leaves experimentation.
- Own the path from data and training through prediction and feedback.
- Version the inputs, code, environment, metrics and model so a result can be traced.
- Automate checks and promotion with explicit quality gates, not unconditional deployment.
- Monitor data, model quality and service health, then define who responds.
What is MLOps?
MLOps (machine learning operations) is the engineering practice of developing, releasing and maintaining systems that produce machine-learning predictions.
Tests should cover source data, transformations and model behavior because each can change independently from application code.
| Lifecycle part | Question it answers |
|---|---|
| Data preparation | Are these inputs valid and fit for this use case? |
| Training and evaluation | Can the model be reproduced, and does it meet the agreed baseline? |
| Release and serving | Can the approved version run in the target environment? |
| Monitoring | Does live behavior remain useful and operationally healthy? |
1. Treat the full ML lifecycle as a product
For a purchase-risk model, for example, define whether a missing transaction amount is rejected or handled by an approved fallback. That choice determines how the calling service and operations team respond when an input is incomplete.
- Task: state the user or business decision, prediction unit and outcome measure.
- Data path: record source systems, transformations, feature meaning and access boundaries.
- Serving contract: document input schema, output meaning, error behavior and caller expectations.
- Ownership: name who reviews releases and responds to production alerts.
For a spend feature, the value could be measured in dollars during training but cents in production. Define units and transformations so tests compare equivalent inputs across both paths.
For time-based features, record the event time and the cutoff available to the prediction. A query that includes events after that cutoff can leak future information into training or evaluation.
2. Make every result reproducible
A reproducible release links its approved model to the run that produced it, along with the artifacts and settings needed to explain the result.
| Record | Why keep it | Useful check |
|---|---|---|
| Code revision and configuration | Identifies the implementation and settings | Can a teammate locate the exact reviewed revision? |
| Data and feature lineage | Explains what the model learned from | Can the run identify its data snapshot and transformations? |
| Environment and dependencies | Helps reproduce execution and diagnose compatibility | Are training and serving requirements recorded? |
| Metrics and evaluation set | Shows why a candidate was accepted | Are metric definitions and baseline documented? |
| Model artifact and release state | Connects a prediction service to its approved version | Can the deployed version be traced and rolled back? |
Training jobs can include stochastic operations and hardware-dependent calculations. When bit-for-bit equality is unrealistic, set an acceptable comparison tolerance and save the seed and environment details that help explain differences.
A registry can associate a model version with its training run, tags and aliases, as MLflow documents. It does not set your release policy, so define who may approve and promote a candidate.
Use immutable version identifiers in records and releases. Human-readable aliases can point to the model currently serving a role, but record the concrete version each deployment resolved to. This makes it possible to determine what was live at a particular time even after an alias changes.
Reproducibility has limits. Some data may be restricted, changing or expensive to retain. Preserve permitted identifiers, schema, transformation version, access conditions and run metadata needed for an audit.
Follow retention rules and keep sensitive records in approved systems. These records can preserve lineage without copying data into a tracking tool.
Versioning also makes rollback practical. Keep the previous approved model and its serving configuration available according to the service’s recovery plan. A rollback should restore a known deployment, including compatible feature code and preprocessing alongside the older model version.
How to operationalize a machine-learning model step by step
Automate repeatable checks and release steps, while making the promotion criteria explicit.
Google Cloud’s guidance notes that ML CI checks extend beyond code to data and models, while CD may deliver a training pipeline that can produce a prediction service. CT retrains models when an appropriate trigger occurs. These activities do not imply that every trained candidate should automatically replace the live model.
Step 1: Check inputs and pipeline changes
Run tests when code, pipeline definitions or relevant data contracts change. Validate schemas, required fields and known domain rules before expensive training starts. A schema check can catch a missing or renamed field, while a transformation test can check that a known input produces the intended feature representation.
Keep these checks close to the pipeline that consumes the data. This small Python example checks that a prediction request includes the fields and types its model contract expects. It is a contract check, not a substitute for validating data ranges or business rules.
Save the example in a file named validate_input_contract.py and run the command shown below.
python3 validate_input_contract.pypayload = {
"customer_tenure_months": 12,
"monthly_spend": 49.0,
}
contract = {
"customer_tenure_months": int,
"monthly_spend": float,
}
missing = [name for name in contract if name not in payload]
wrong_types = [
name
for name, expected_type in contract.items()
if name in payload and type(payload[name]) is not expected_type
]
if missing or wrong_types:
print(f"Missing fields: {missing}")
print(f"Wrong types: {wrong_types}")
else:
print("Input contract: valid")The terminal capture shows the exact run and its result.
pankaj@codeforgeek:~$ python3 validate_input_contract.py
Input contract: valid
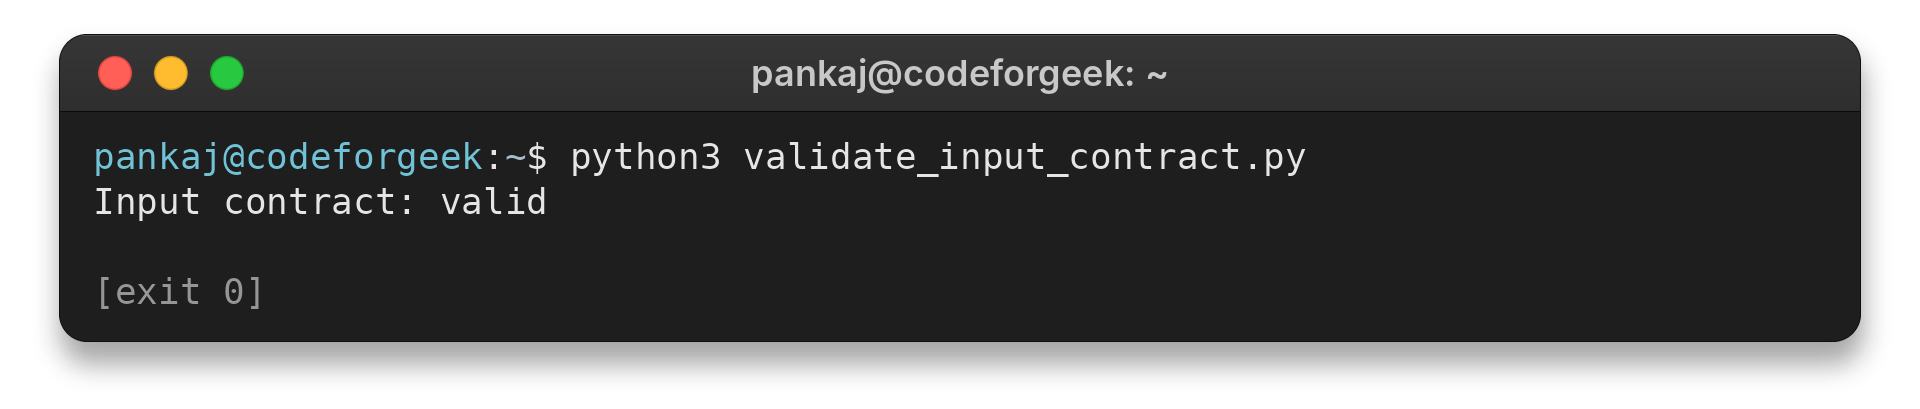
A contract failure should stop or quarantine the input before training or prediction uses it. Add checks for allowed ranges and domain-specific conditions only after the team defines those rules, since type validation alone cannot establish that an input is meaningful.
Other fields need checks beyond their type. A timestamp may need to fall within an allowed freshness window, a category may need to belong to an approved set, and a numeric value may require a documented unit and range. Distinguish a missing field from an explicit null so the pipeline applies the intended behavior.
Step 2: Train and evaluate a candidate
Run training as a traceable job and save the candidate, configuration and evaluation results together. Compare the candidate against a baseline using a metric selected for the product task, and check that the evaluation data is suitable for the decision being made.
Evaluation should include relevant slices when aggregate performance could conceal a failure for a group or operating condition. Test risks identified for that model and document how an approver interprets results.
Model evaluation should preserve the separation between data used to fit a candidate and data used to judge it. If records or related events cross that boundary, the score may reflect information the deployed model would not have had.
The split method depends on the use case. Time-dependent data often calls for a chronological split, while grouped observations may need group-aware separation so related examples do not appear on both sides.
A single holdout can miss seasonal variation, so repeat evaluation over historical cutoffs when release risk warrants it. Keep the observation window consistent and compare performance at each cutoff, not only the average. These backtests show how results behaved across known periods, but they cannot guarantee the next period will match.
For small evaluation slices, report the sample count beside the metric. A very small group can produce an unstable score, so treat it as a signal for review rather than conclusive evidence.
Record the evaluation set’s purpose and its limitations with the run. A metric without a defined population or evaluation period is hard to compare with a later result. If labels arrive late, record when the measurement becomes reliable and avoid treating an early proxy as the final quality measure.
For a binary classifier, the decision threshold affects the balance between false positives and false negatives. Review how those errors change the downstream action before choosing a passing threshold.
Regression tasks benefit from examining the direction and spread of residuals as well as average error. Ranking systems can inspect the quality of the top results when those positions drive the user’s next action.
If a score is presented as a probability, check whether predicted confidence corresponds to observed outcomes across relevant ranges. Calibration can matter to an application that uses the score for prioritization, even when its ordering is useful.
Metrics also need stable definitions. Keep the calculation, threshold and evaluation data reference with the candidate so a later run does not silently change what “pass” means. If the business objective changes, update the criteria deliberately and compare the new decision with the previous release rather than interpreting unlike metrics as a trend.
For recurring training, record the trigger and the acceptance step separately. A schedule or new-data event can start a job, but a successful run only means the pipeline completed. The resulting model still needs to pass validation and any approval required for its risk level before traffic moves to it.
This distinction matters when a pipeline is retried after a transient failure. Make jobs safe to repeat by recording their inputs and outputs and by avoiding side effects that create duplicate production releases. Orchestration can coordinate tasks, but the workflow should also define how failed stages are surfaced and whether an operator must resume them.
Serving checks should reflect how the application calls the model. Verify the expected fields, serialization and response shape, then check behavior for malformed or incomplete requests. A service can return a response while violating the caller’s contract, so include a consumer-side check where the teams control both ends.
Consider resource and access constraints before a release. Model loading time, memory use and dependency compatibility can affect service capacity. Credentials and data permissions should follow the deployment environment’s controls rather than being copied into training artifacts or logs.
Step 3: Package and test the serving path
Confirm that the model can load in the target runtime and that the service handles the documented input contract. Test representative requests, error handling and deployment constraints before production. A model may perform well offline and still fail because a required package is missing or the service receives a different feature shape.
For batch scoring, treat each output set as a versioned result. Record its input window and model version, validate expected rows and output fields, and publish only after the whole run completes. Define how late records are handled and make reruns safe for downstream consumers.
For an online endpoint, the request deadline is part of the serving contract. Watch tail latency and queueing alongside average response time, then set timeouts and concurrency limits to fit the caller’s budget. Exercise cold starts and concurrent requests using the same packaged runtime planned for release.
Step 4: Promote with a recorded decision
Promote only after required tests pass and the accountable reviewer accepts the evidence. Record the model version, code and configuration, evaluation result, approval and deployment target. Start with a controlled environment or limited exposure when that fits the system, then expand only if the operational and product signals remain within agreed bounds.
A shadow deployment compares candidate predictions with the live model while the candidate does not control user-facing decisions. A canary sends a limited share of actual traffic to the candidate. Choose between them based on whether the goal is safe comparison or controlled exposure, and write the rollback signal before either begins.
Automation should make a safe decision repeatable while preserving responsibility for the decision. Keep manual approval where policy, safety or business risk requires it. On a low-risk internal task, the team may automate more of the path after it has evidence that checks reliably detect the failures that matter.
CI, CD and CT can be introduced incrementally. First make one training run repeatable, then automate validation and artifact recording.
Add scheduled or event-based retraining only when new data, a monitoring signal or a planned cadence makes it useful. A pipeline without a clear trigger or acceptance rule can create churn rather than quality.
4. Monitor predictions and the system around them
A successful request confirms that the endpoint responded. It does not confirm that the prediction remains useful for the live population.
Monitor operational signals such as error rates, latency and resource use alongside input and output summaries. When reliable labels become available, compare model outcomes with the agreed quality measures. A model may appear healthy at the infrastructure level while its data distribution has changed or its predictions no longer support the intended decision.
- Input schema or missing fields: may indicate an upstream contract change or incomplete data. Quarantine invalid inputs and contact the data owner.
- Feature distribution shift: serving inputs differ from reference data. Investigate the source, seasonality and transformation parity.
- Delayed quality decline: predictions may be less useful after labels arrive. Review affected slices and compare them with the baseline.
- Latency or error increase: serving code, dependencies or capacity may be unhealthy. Follow the service runbook and assess rollback criteria.
Input drift describes a change in the distribution of incoming features. A change in the relationship between inputs and outcomes is a different concern, and it may become visible only after labels arrive. Keep these signals separate in dashboards so a change in traffic composition is not mistaken for a confirmed loss of predictive quality.
Set alert thresholds against a baseline and a measurement window. A one-hour spike may be noise for a low-volume endpoint, while a sustained increase can warrant action. Account for known seasonality, traffic volume and delayed labels, and record why each alert threshold is meaningful for the service.
Monitoring data also needs boundaries. Avoid logging raw sensitive inputs by default, and choose aggregation and retention that meet the system’s privacy and operational requirements. A trace identifier can help connect a failed request to service logs without copying its full payload into every dashboard.
Labels can arrive late or may not exist for every prediction. Until an outcome is measurable, track proxy signals carefully and state what they cannot establish. Do not present a stable input distribution as proof of model accuracy, or a changing distribution as proof that retraining is necessary.
Every alert needs an owner, a threshold rationale and an action. An alert without a response path produces noise. Document who investigates, which dashboards and artifacts they need, when to pause promotion, and what evidence permits resuming service.
Monitoring also feeds back into the lifecycle. An investigation may reveal a data issue to fix, a feature definition to revise, a model to retrain or a product assumption to revisit. Retraining is one possible response, not the default, because a model trained on faulty or unrepresentative new data can make the system worse.
Edge cases to plan for
Operational problems often occur at the boundaries between teams and lifecycle stages. Decide in advance how the system handles changes, uncertainty and incomplete feedback.
| Case | Symptom | Practical response |
|---|---|---|
| Training-serving skew | The live feature differs from its training value | Test transformation parity with representative cases |
| Delayed ground truth | Quality cannot be assessed when a request arrives | Evaluate prediction outcomes when labels arrive |
| Rare classes or small slices | Aggregate scores hide weak performance | Choose risk-based slice checks and report sample limits |
| Data access restrictions | Data cannot be copied into tracking | Store permitted lineage and leave data in its governed system |
| Unstable upstream source | Inputs are late, malformed or unavailable | Agree on validation and fallback behavior with the source owner |
| Offline metric passes, service fails | Latency, memory or input contract fails after release | Test the packaged serving path before promotion |
For decisions with legal, financial or safety consequences, define when a person must review a prediction and what evidence they can consider. Record any override with the model version and applicable policy so the decision can be understood later.
Teams also differ in how much automation they need. A model updated rarely and served to a small internal workflow may need versioned runs, review and basic monitoring before it needs a complex orchestrator. A system that retrains frequently or serves a high-impact decision may need stronger automation, access controls, audit trails and rollback procedures.
Governance should fit the model’s consequences. Identify data access rules, retention requirements, review responsibilities and the evidence required to approve a change. Keep those controls part of the workflow rather than relying on a separate document nobody checks during release.
Do not confuse a tool inventory with an operating process. A registry, orchestrator or monitoring dashboard helps only when it answers a concrete question, has dependable inputs and connects to an owner’s action. Select tools after the team can describe the process and the failure it is meant to prevent.
Conclusion
MLOps improves the repeatability and support of a model-backed product. Keep release evidence and rollback context available to the team that operates it.
For background on model choices, see CodeForGeek’s machine learning frameworks for web development and its neural network basics guide. The primary sources for MLOps practices include Google Cloud’s MLOps architecture guidance, AWS’s MLOps overview and MLflow’s model registry documentation.
FAQ
These answers cover common decisions when a team moves from model experiments to a maintained service.
How is MLOps different from DevOps?
MLOps uses software delivery practices while also managing data, model evaluation, training pipelines and production model behavior. Those data and model lifecycle needs extend beyond conventional code deployment.
Does MLOps require automatic retraining?
No. Continuous training is one MLOps practice. Retrain on a justified schedule or trigger, evaluate the candidate, and promote it only when it meets the release criteria.
What should a team monitor after deploying a model?
Track service health such as errors and latency, input data and feature changes, and model quality when reliable outcome labels become available. Assign an owner and response for each alert.
How can a team start using MLOps?
Choose one model-backed use case, define its success and serving contract, make a training run traceable, add data and model checks, and establish release and monitoring ownership before expanding automation.