New to Rust? Grab our free Rust for Beginners eBook Get it free →
Extract SERP Data With Zenserp API

Search results can be useful in a script, but a program needs them in a form it can read. Zenserp’s v2 Search API returns Google search results as JSON for a Node.js program to process.
I’ll show how to make the request in Node.js and keep only result links that have a title and URL.
TL;DR
Use Zenserp’s v2 Search API to request Google’s result JSON, then filter its organic array for links with a title and URL.
- Use Node.js 18 or later for built-in fetch().
- Keep the API key in an environment variable, not in the source file or URL.
- Set num to no more than 100 per page and use start for another offset.
What Is SERP Data in Zenserp?
SERP data is the structured information on a search engine results page. Zenserp places result entries in an organic array, but that array can also include feature objects such as question and video panels.
A standard result in Zenserp’s sample has fields you can use to identify and display a link. Its position records where it appeared in that response and can change on a later request, even when the query is the same.
| Field | What it tells you | How the example uses it |
|---|---|---|
| Position | The item’s position in the returned page sample. | Print it to keep the listed order. |
| Title | The result’s displayed title when the item is a link. | Filter for a string before printing. |
| URL | The result URL shown in the response. | Keep it with the title for downstream processing. |
| Destination and Description | Additional fields in Zenserp’s sample result. | Use them only if your task needs them. |
| Questions or Videos | Feature data rather than a normal result link. | Skip the entry when you need only title-and-URL pairs. |
How to Extract SERP Data With Zenserp in Node.js
Use the documented v2 search endpoint, pass the query and locale as URL parameters, and read only the response fields your program needs. The steps below use one source file for both a local sample and an optional live request.
Step 1: Keep the API key out of the file
Create an API key in your Zenserp account, then provide it to the Node process through the environment. It goes in the recommended apikey header and stays out of the JavaScript source and query string. A header also keeps the credential out of request URLs that may appear in logs.
read -srp 'Zenserp API key: ' ZENSERP_API_KEY
export ZENSERP_API_KEY
printf '\n'
The prompt masks the characters as they are entered. The export makes the variable available to child processes launched from that shell.
A new terminal session starts without this variable. Run the setup again before testing from there.
Step 2: Save the request and parser
Save this program as extract_serp_data.js. The default path makes a live GET request. The –sample option selects a short fixture from Zenserp’s public response example so the parsing logic can be checked without an API key.
const ENDPOINT = "https://app.zenserp.com/api/v2/search";

// One organic object and one feature object from Zenserp's published homepage sample.
const sampleResponse = {
  organic: [
    {
      position: 1,
      title: "Pied Piper of Hamelin - Wikipedia",
      url: "https://en.wikipedia.org/wiki/Pied_Piper_of_Hamelin",
      destination: "https://en.wikipedia.org/wiki/Pied_Piper_of_Hamelin",
      description: "The Pied Piper of Hamelin is the titular character of...",
    },
    {
      position: 2,
      questions: [
        { question: "What is the meaning of the Pied Piper?" },
      ],
    },
  ],
};

function printOrganicLinks(payload) {
  const entries = Array.isArray(payload.organic) ? payload.organic : [];
  const links = entries.filter(
    (item) => Number.isInteger(item.position)
      && typeof item.title === "string"
      && typeof item.url === "string",
  );

  console.log(`Organic links: ${links.length}`);
  for (const item of links) {
    console.log(`${item.position}\t${item.title}\t${item.url}`);
  }
}

async function fetchSerp() {
  const apiKey = process.env.ZENSERP_API_KEY;
  if (!apiKey) {
    throw new Error("Set ZENSERP_API_KEY in the process environment before a live request.");
  }

  const url = new URL(ENDPOINT);
  url.searchParams.set("q", process.env.SERP_QUERY || "Pied Piper");
  url.searchParams.set("gl", "us");
  url.searchParams.set("hl", "en");
  url.searchParams.set("num", "10");

  const response = await fetch(url, { headers: { apikey: apiKey } });
  if (!response.ok) {
    const body = await response.text();
    throw new Error(`Zenserp HTTP ${response.status}: ${body.slice(0, 200)}`);
  }
  return response.json();
}

async function main() {
  const payload = process.argv.includes("--sample")
    ? sampleResponse
    : await fetchSerp();
  printOrganicLinks(payload);
}

main().catch((error) => {
  console.error(error.message);
  process.exitCode = 1;
});
The URL object encodes the query safely instead of concatenating a phrase into a URL by hand. The q parameter carries the search phrase, gl selects country context, and hl sets language. URLSearchParams encodes spaces and punctuation in the phrase before sending it.
The num parameter sets page size. Use the documented location parameter to target a place, device for desktop, mobile, or tablet, and start for a later offset.
Fetch resolves for HTTP responses even when the status indicates failure, so check response.ok for successful 2xx statuses before parsing JSON. The example includes a short provider error excerpt, while a network failure rejects the promise and reaches the catch handler.
Step 3: Run the parser against the sample
The sample option reads the local fixture and makes no API request. I ran it from the named source file, and the output below is the captured result.
The terminal shows the complete command and its output:
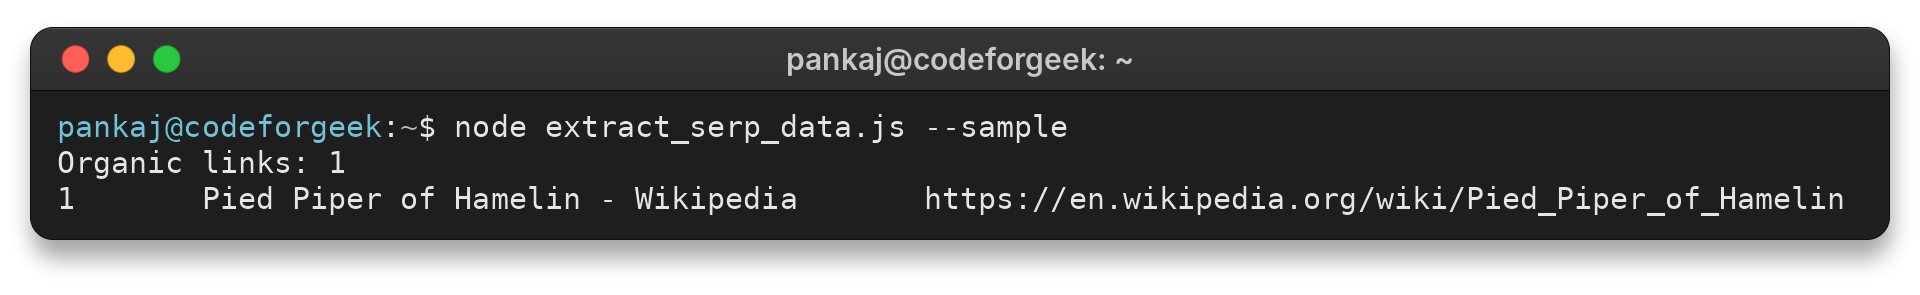
pankaj@codeforgeek:~$ node extract_serp_data.js --sample
Organic links: 1
1	Pied Piper of Hamelin - Wikipedia	https://en.wikipedia.org/wiki/Pied_Piper_of_Hamelin

[exit 0]
For a live query, run the same file without –sample after setting the key, and pass a phrase in SERP_QUERY, for example SERP_QUERY=’best hiking boots’ node extract_serp_data.js. The response varies with the query and request settings, so inspect its shape before using fields in later code.
Step 4: Keep the result shape you need
If the next task needs a JSON file rather than terminal lines, change printOrganicLinks() to return its filtered array, then write that array with Node’s file-system module.
If the next program displays a returned title or description in a web page, escape it at the HTML rendering boundary. JSON parsing leaves those values as data, not trusted markup.
What Should You Check When Results Look Wrong?
Separate request failures from response-shape and targeting issues. Check the HTTP status first, then confirm the query and locale before changing the parser.
| Case | Symptom | Check |
|---|---|---|
| Missing or rejected key | The program stops with a non-2xx status or reports that the key is missing. | Confirm the environment variable is available to this process and inspect the returned HTTP status. |
| Network or HTTP failure | fetch() rejects, or response.ok is false. | For a network error, check connectivity and DNS. For an HTTP response, read its status and returned error text, then compare the request with the current API docs. |
| Zero links printed | The request completes, but the filter finds no title-and-URL objects. | Inspect whether organic is an array and whether its entries are link objects or feature data. Check the query and requested country/language values. |
| Unexpected SERP | The same phrase produces a different page or ordering. | Confirm that the requested country and language match the intended search scope. Check location or device when the task requires a specific context. |
| Need a deeper page | The first response has fewer entries than the task needs. | Zenserp allows no more than 100 results in one request. Use start to request another offset. Results from separate offsets can overlap or contain fewer entries. |
- Start at offset 0 and advance start by the requested page size. The guide illustrates 0, 10, and 20 for pages of ten.
- Keep the query and request parameters consistent across one pagination run. Record each requested offset beside its returned rows.
- URLs may recur across pages. Deduplicate by URL when the task needs unique destinations, or retain page membership when you need a response-by-response record.
- A page can return fewer entries than requested. Stop on an empty page or when the task has enough rows, and track the collected row count separately from the last offset.
Built-in fetch() is available in Node.js 18 and later. On an older runtime, use a supported HTTP client such as node-fetch or Axios in Node.js. Keep the same endpoint and key-handling rules.
Conclusion
Use sample mode to confirm the parser, then run the same source file with the live request enabled and a phrase set in SERP_QUERY.
For several search phrases, the migration guide also lists a v2/batch endpoint that accepts multiple queries in one call. Review its request and response schema separately before adapting this single-search parser to a bulk job.
For parameter details, use the Zenserp migration guide and the Node.js Fetch documentation. For related CodeForGeek guidance, see reading data from a REST API in Node.js.
FAQ
These answers cover result depth, feature entries, and the Node.js runtime needed for the request shown above.
Can one Zenserp request return more than 100 results?
Zenserp allows up to 100 results per request. Use the start offset to request another page. Each response may contain fewer results, and adjacent pages can overlap.
Why can an item in the organic array lack a title and URL?
The array can contain SERP-feature data, such as questions or videos. Filter for the title and URL fields when the program needs ordinary result links.
Does this example need a separate fetch package?
No. It uses the global fetch available in Node.js 18 and later. An older runtime needs a compatible HTTP client, such as node-fetch or Axios.